In short: Load average on a Linux server is the average number of processes that were using a CPU, waiting for a CPU, or waiting for disk input/output over the last 1, 5 and 15 minutes. You read it against the number of CPU cores. On a 4-core server, a value around 4 means the CPUs are busy all the time. If the value stays above the core count for a long time, work is queuing up.
Anyone who runs a VPS or a server sees three numbers in the first line of uptime or top. This article explains what those three numbers mean, when you should worry, and how to find the cause step by step when the load is high.
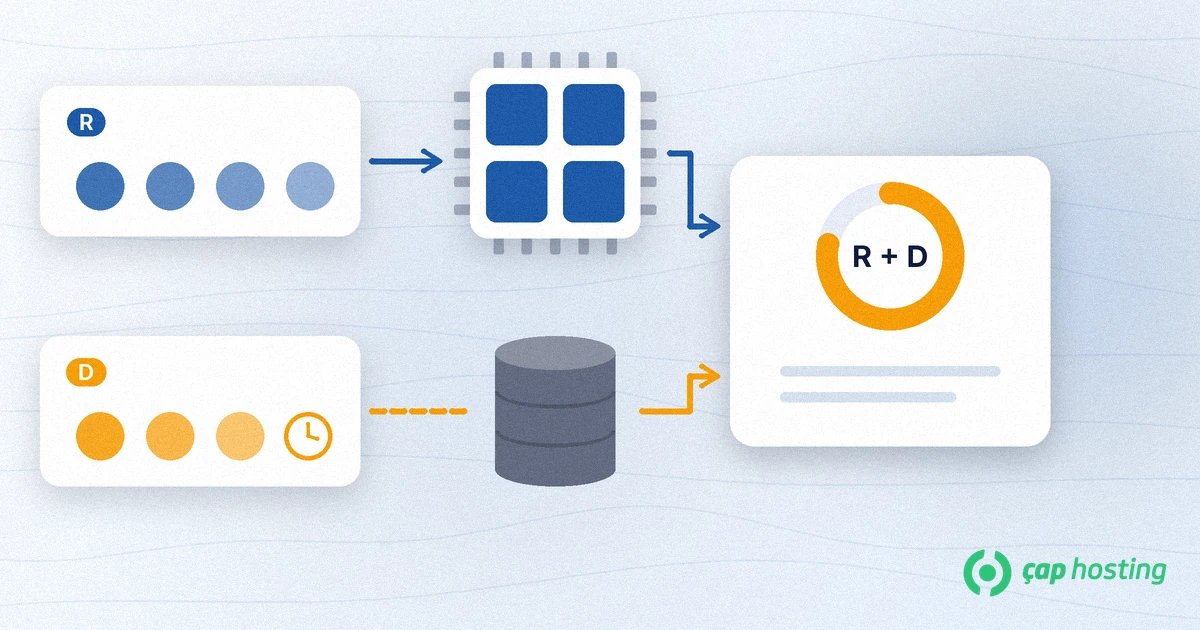
According to the Linux /proc/loadavg documentation, the first three fields are the number of jobs in the run queue (state R) or waiting for disk I/O (state D), averaged over 1, 5 and 15 minutes. uptime and top show the same numbers. So load average measures waiting work, not just CPU usage:
As Brendan Gregg explains in his deep dive into Linux load averages, these are not simple averages but exponentially damped ones, where older values fade out over time. That is why a sudden spike shows up first in the 1-minute value while the 15-minute value reacts more slowly.
If uptime prints load average: 3.90, 2.10, 0.80, for example, you are looking at the averages for the last 1, 5 and 15 minutes. Look at two things together: how big the values are and which way they are moving.
| Pattern | What it means |
|---|---|
| 1 min > 5 min > 15 min | Load is rising. A job, traffic peak or scheduled task has probably just started. |
| 1 min < 5 min < 15 min | Load is falling. A busy period happened and is passing. |
| All three similar | Load has been steady for a while. Compare it with the core count. |
To judge the size of the value, first find out how many processing units the server can use:
nprocThe uptime manual says it plainly: load averages are not normalized for the number of CPUs. A load of 1 means a single-CPU system is busy all the time, while on a 4-CPU system it means the machine was idle 75 percent of the time. For a quick reading, divide the load average by the nproc result. Below 1 there is usually no queue; staying above 1 for a long time means processes are waiting. This is not a fixed threshold for every server. Tracking your own server's normal range over time is the most reliable guide.
No. Because Linux also counts processes in state D, load average can be high while CPU usage is low. In that case the bottleneck is usually the disk: slow storage, an application writing too many logs, a large backup job, or swapping because memory has run out. Gregg also notes that some lock waits are counted, so instead of deciding from one number, confirm the cause separately.
The opposite can also happen: CPU usage can look close to 100 percent while load average stays below the core count. That means the CPU is busy but little work is waiting, which is not a problem on its own. What matters is how long work waits. If users do not notice any slowness and the values are within your normal range, you usually do not need to act.
uptime and the core count with nproc.vmstat 1 5. According to the vmstat manual, the r column shows runnable processes, b shows processes blocked waiting for I/O and wa shows time spent waiting for I/O. If r is above the core count, look at the CPU; if b and wa are high, look at the disk.st is time stolen from the virtual machine, meaning the hypervisor gave it to other work. If it stays high, the problem may be on the infrastructure side rather than in your application, so share it with your provider. To see how resources are allocated, read our article on VDS vs VPS.top to see which process uses the most CPU. To list processes in state D, you can use:ps -eo state,pid,cmd | grep '^D'free -h to see memory and swap usage. When memory is always full, the system writes to swap, which adds disk waiting. You can add swap space if needed, but for a lasting fix review how much memory the application needs.Load average is an indicator, not an alarm on its own. What really helps is knowing the range your server runs in on a normal day. To watch CPU, RAM and disk together, use our guide on how to monitor server resource usage. If visitors say your site feels slow, server load is only one possible cause; see why a website is slow for the others.
To sum up: compare the three numbers with the core count, check whether the load is rising or falling, separate CPU from disk when it is high, then find the process. Following that order, you can usually see the cause of a load problem within minutes.
There is no single value for every server. Compare the value with the core count from nproc. If it stays above the core count for a long time, processes are waiting.
No. CPU percentage shows how busy the processor is. Load average is the average number of processes that are running, waiting for a CPU or waiting for disk, so it can be high while CPU usage is low.
The averages for the last 1, 5 and 15 minutes together show the direction of the load. If the 1-minute value is the largest, load is rising; if it is the smallest, load is falling.
Find the cause first. A reboot can lower the load for a while, but if the cause is an application, a scheduled task or a disk bottleneck, the problem soon comes back.
 Copyright © 2026 All Rights Reserved
 Turkey (Türkçe)
 Worldwide (English)